Testing and Evaluation
Proving the system does what Chapter 4 said it must, including the one thing that cannot be proved by looking at it.
Chapter 6 proves the system does what Chapter 4 said it must. Not by claiming it, by measuring it.
The unusual thing about your Chapter 6, and the thing that makes it strong, is that it also lists the bugs the testing found. Most students hide those.
Pages 104 to 114.
Choosing how to test, and saying why
Your chapter does something most do not: it justifies its testing strategy before applying it, and it names two strategies it rejected, with reasons.
| Strategy | Used? | Why |
|---|---|---|
| Functional testing against the specified requirements | Yes | Chapter 4 produced a numbered, traceable requirement set from evidence. So the system can be checked against the same specification the data produced, closing the loop from survey finding to requirement to verified behaviour. |
| Concurrency and data integrity testing | Yes | The central design decision of Chapter 5 is a correctness claim about what happens when people act at the same moment. This kind of bug never appears in single-user testing. It has to be provoked deliberately. |
| Non-functional measurement | Yes | Three of the adoption conditions organisers named are non-functional: reliability, ease of use, responsiveness. A target that is specified but never measured is not really a requirement. |
| Usability testing with a participant panel | Considered, not done | The system reached a testable state too close to the deadline to recruit and run one properly. Running it badly would have produced a number with no evidential value. Stated as a limitation, not quietly omitted. |
| Benchmarking against a commercial platform | Rejected | Not on time, on validity. Chapter 2 established that no existing platform combines the three capabilities this system integrates, so there is nothing to make a like-for-like comparison against. |
It shows the testing was designed rather than assembled from whatever was convenient. An examiner who sees you considered and rejected benchmarking, with a reason, will not ask why you did not benchmark.
The ten tests
| ID | What it checks | Result |
|---|---|---|
| TC-01 | An organiser completes and publishes an event. And an event missing capacity or inventory is refused, naming the missing field | Pass 4 checks |
| TC-02 | Ticket, room and add-on all created on one event. And reducing a total below what is already booked is refused | Pass 6 checks |
| TC-03 | A traveller books across two resource kinds in one action | Pass 8 checks |
| TC-04 | A booking that would push past the event capacity ceiling is refused, and nothing is decremented | Pass 5 checks |
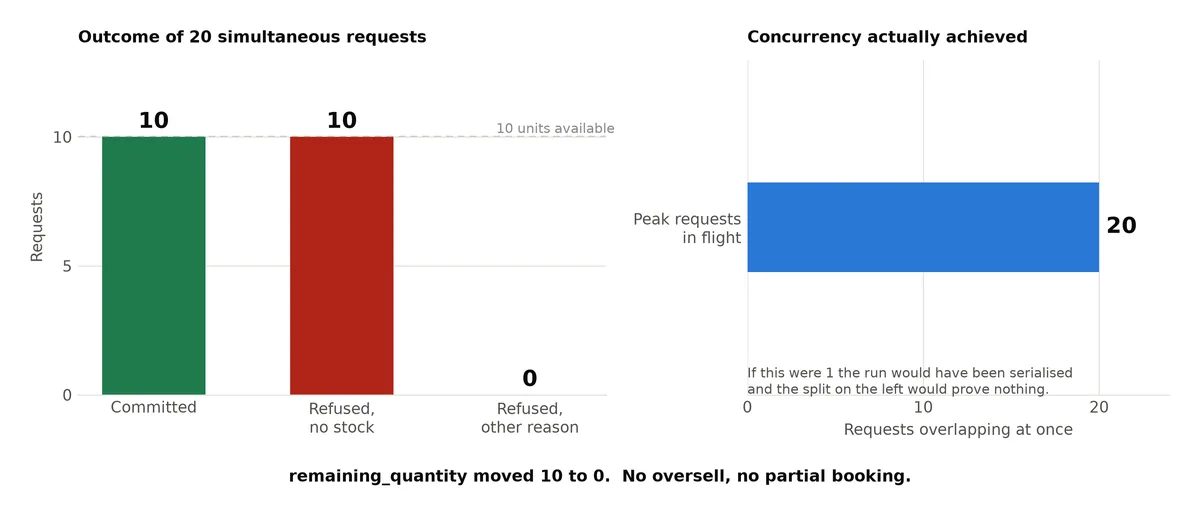
| TC-05 | 20 booking requests fired at exactly the same moment at a resource holding 10 units | Pass 7 checks |
| TC-06 | A valid QR token admits the guest and records the timestamp | Pass |
| TC-07 | The same token presented a second time is refused as a replay | Pass |
| TC-08 | The dashboard updates with no refresh when a booking commits in a different session | Pass |
| TC-09 | Cross-guest and cross-property reads issued directly against the API, going around the interface | Pass 9 checks |
| TC-10 | Every screen at 375, 768 and 1440 pixels wide | Pass 39 screens |
Those two cannot be satisfied by driving the screens.
TC-05 needs genuine simultaneity, which a person clicking a button cannot produce.
TC-09 deliberately bypasses the interface, because a rule that only lives in the interface would pass a screen test while leaving the data exposed.
Both were run programmatically with scripts, not by hand.
TC-05, the test the thesis rests on
Someone will ask: "How do you know the requests really happened at the same time?"
The test asserts peak overlap as well as the outcome, and it recorded 20 requests in flight at once.
That assertion is what makes the rest of the test mean anything. If the requests had been quietly serialised, run one after another instead of together, the final numbers would have looked identical while proving nothing about the locking. They did overlap, all 20 at once, and no oversell occurred.
Every refusal named the resource that ran out, which is what lets the booking panel mark the single failed line rather than discarding the whole basket.
TC-09, access control tested properly
Nine checks, all issued with real user sessions against the public key, so what passed is the database policy, not a screen hiding a button.
- A guest cannot read another guest's booking by its id
- A guest listing bookings sees only their own, not all 288
- An organiser cannot read bookings on another property's event
- An organiser cannot rename another property's event
- An anonymous caller cannot invoke the booking function
- An anonymous visitor cannot read a draft event
- A guest cannot read another guest's profile
- An organiser can read the profile of a guest booked onto their own event
- That widening does not let an organiser browse the whole user table
Checks 7 to 9 were added when the profile rule was widened so an organiser could put a name to a booking. They exist to hold the boundary, because a rule widened once can be widened carelessly again.
The measured numbers
| ID | Target | Measured | Verdict |
|---|---|---|---|
| NFR-01 | Event browse loads under 2 seconds | 501 ms p95, 400 ms p50, n = 30 | Pass |
| NFR-01 | Event detail loads under 2 seconds | 336 ms p95, 252 ms p50, n = 30 | Pass |
| NFR-02 | A booking reaches every subscribed screen under 2 seconds | 580 ms p95, 265 ms p50, n = 11 | Pass |
| NFR-03 | Still working under concurrent load | 40 concurrent requests, 40 succeeded, 0 failed | Pass |
| NFR-04 | Zero oversell, zero partial booking | Verified by TC-05 | Pass |
| NFR-07 | 3 screen widths, no sideways scrolling | 39 screens clean | Pass |
| NFR-06 | A first-time organiser publishes without training material | Not measured | Unverified |
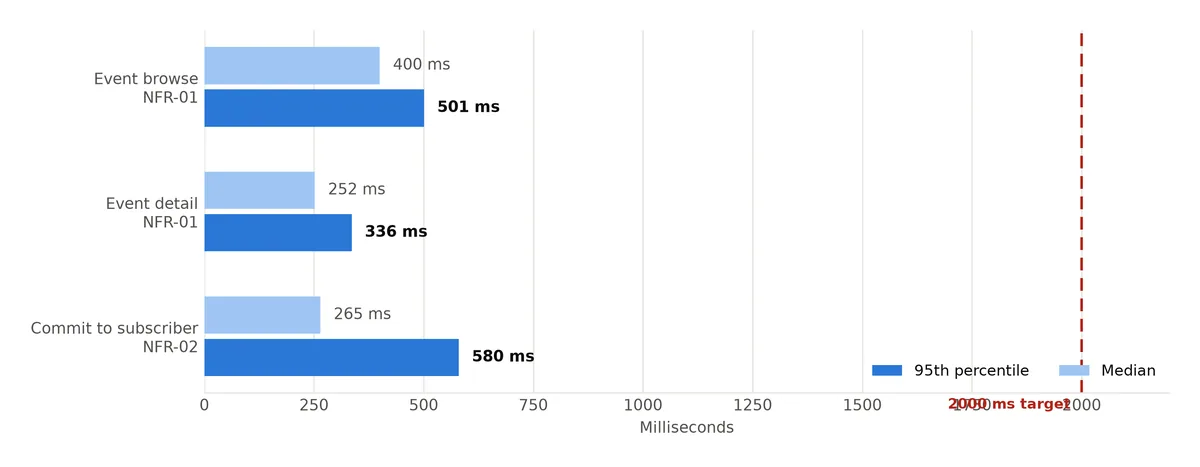
Twelve latency samples were taken for the live-update measurement. One never arrived inside the ten second observation window, and it was the first sample after the channel subscribed, so the reported figure uses 11.
It is stated in the text rather than quietly removed, because a discarded outlier that nobody mentions is indistinguishable from a result that has been tidied. If an examiner spots an n of 11 where you said 12, you have already answered them.
These are prototype figures, measured against a development server with the database hosted in Singapore. Production figures would differ.
The thesis reports them as prototype measurements rather than as production service levels, and you should say the same. Do not claim your system runs at 501 milliseconds for real users worldwide.
The seven bugs, and why they are in the thesis
An evaluation that reports only its final state conceals the work that made the final state trustworthy. Two of these seven would otherwise have produced a false pass, which is the strongest possible argument that the testing earned its place.
- The token generator was invisible to the booking function The booking function locks down which parts of the database it can see, as a security measure. The hosting platform installs the cryptography tools somewhere outside that view, so the random token generator could not be found and every single booking failed. TC-05 caught it immediately, with all 20 requests rejected for the wrong reason. Fixed by widening the locked-down view to include that area, rather than by removing the lock.
- Browser settings were undefined The code read its configuration through a variable key. The framework only puts public settings into the browser bundle when it can see them written out literally, so every part of the page that opened a database connection failed in the browser, while the server-rendered version still looked fine.
- The screenshot evidence was captured from error pages The most instructive of the seven. Because of bug 2, every screen was rendering an error. And since an error page does not overflow its viewport, the responsive test passed against 36 screenshots of a stack trace. It was found by opening the images, not by reading the test output. The capture script now fails the run if any screen rendered an error or rendered empty. If you tell an examiner one story from this chapter, tell them this one. It shows you understand that a passing test is not the same as a working system.
- Organisers could not create an event at all Inserting a row and reading it back checks the read rule on the brand new row inside the same statement. That rule used a helper which reads a snapshot taken before the insert, so it could not see the row being created, and the insert failed with a misleading permissions error. Fixed by checking ownership through the property reference carried on the new row itself.
- Every booking on the dashboard showed the guest as "Guest" The profile rule let a user read only their own row, correct for guests, but it left organisers unable to put a name to a booking. Widened to include guests holding a booking on that organiser's own events, with three new checks confirming the widening did not open the wider user table.
- Sideways scrolling on the browse screen A grid column defaults to a minimum width set by its contents, and a date picker carries a large built-in minimum, which pushed the page to 437 pixels inside a 375 pixel screen. Caught at two of the three widths.
- The cover photos illustrated nothing The seed data used a random image service, so a photograph of an airport terminal appeared above a live music event. Replaced with a typographic panel. The reasoning is worth quoting: on a system whose entire claim is that its information can be trusted, an image of the wrong place is worse than no image at all.
What this evaluation does and does not prove
Your chapter bounds itself explicitly, which is more valuable than overclaiming. Three statements:
What it establishes
That the system meets the specification derived in Chapter 4, and that the concurrency and access-control guarantees hold directly rather than by inspection.
What it does not establish
That coordination actually improved at a real hotel. That would need deployment across a season, measured against a pre-deployment baseline.
What was not tested
Usability with participants. NFR-06 is specified but unverified. The chapter names this as the weakest point of the evaluation.
If they ask you
How do you know your concurrency test actually ran concurrently?
Because the test asserts peak overlap as well as outcome, and it recorded 20 requests in flight at once.
That assertion is what makes the rest of the result meaningful. If the requests had been serialised by the runtime rather than held by the database lock, the outcome would have looked identical while proving nothing about the locking discipline.
You report seven defects. Does that not weaken your evaluation?
It is the opposite. Two of them would otherwise have produced a false pass. The most instructive is the third: the responsive test passed against 36 screenshots of an error page, because an error page does not overflow its viewport.
That was caught by opening the images, not by reading the test output, and the capture script now fails the run if any screen rendered an error. An evaluation that reports only its final state conceals the work that made the final state trustworthy.
Why did you not run a usability test?
The artefact reached a testable state too close to the submission deadline to recruit and run a System Usability Scale panel with adequate rigour, and running it badly would have produced a number with no evidential value.
It leaves NFR-06 specified but unverified, which Section 6.6 names as the weakest point in the evaluation and Section 7.5 carries into the future recommendations.
The evaluation effort that was available went to the two claims that could not be established any other way, concurrency integrity and access control, rather than being spread thinly across everything.
Why did you not compare your system against Eventbrite?
On validity grounds rather than time. Chapter 2 establishes that no existing platform combines the three capabilities this system integrates, so there is no comparable artefact for a like-for-like benchmark.
Comparing against Eventbrite on ticketing, or against a hotel booking platform on rooms, would test each platform on the half of the problem it was built for and would say nothing about coordination across resource kinds, which is the thing being studied.
Your response times look very fast. Are they realistic?
They are real measurements, not estimates, but they are prototype figures. They were taken against a development server with the database hosted in the Supabase Singapore region, and the thesis reports them as prototype measurements rather than as production service levels.
Production figures on a distributed deployment would differ. What the numbers establish is that nothing in the architecture is anywhere near the 2 second targets, not that these are the speeds a live service would deliver.
Chapter 6 evaluates the artefact against the specification from Chapter 4. I selected three evaluation strategies and rejected two, with reasons stated. Ten test cases, each traced to the requirement it verifies, and all ten pass. The two most consequential, concurrency integrity and access control, were run programmatically rather than through the interface, because interface-driven testing cannot establish either property. Six non-functional targets were measured rather than estimated. The chapter also reports seven defects the testing found, two of which would otherwise have produced a false pass, and it bounds what the evaluation establishes: conformance to the specification, not realised improvement in the field.